
Unified Math
DeepCausality treats algebra, linear algebra, geometry, topology, and effect propagation as a single mathematical surface. The same Functor, Monad, and CoMonad operations run over tensors, matrices, multivectors, manifolds, and propagating effects. The same trait tower states what laws a scalar obeys, whether that scalar is a natural number, an integer, a rational, a real, a complex number, a dual number, or an element of 𝔽₂.
Seventeen crates carry the mathematics, and they live together under deep_causality_unified_math/. That is a directory grouping, not a facade: each is its own Cargo package with its own public API, so a use statement names the package and never the folder.
Three of them carry the foundation:
deep_causality_numholds the representation traits: what a machine number can do.deep_causality_algebraholds the algebraic traits: what laws it obeys.deep_causality_haftholds the Higher-Kinded Type machinery that lets a container join the composition surface.
deep_causality_metric sits horizontally across every layer, defining metric signatures once, so a general-relativity calculation in the tensor layer and a particle-physics calculation in the multivector layer share sign conventions. Two dependencies reach in from outside the folder: deep_causality_ast, which tensor and uncertain build on, and deep_causality_par, which supplies the MaybeParallel marker to fft and topology. Both live under deep_causality_utils/.
This page develops that claim in five steps. It first states what the uniformity buys, then maps the crates and their dependency order. It next covers the two things every layer shares: the algebraic tower that says which laws a scalar obeys, and the single alias that fixes the working type. It then describes the composition surface itself, container by container. It closes with a worked example that crosses four layers in one chain, and with what that composition buys in measured precision.
Why uniform mathematics matters
Section titled “Why uniform mathematics matters”Scientific code usually pays a hidden tax. Every time the math crosses a domain, from a mesh walk to a tensor contraction, from a tensor to a rotor, from a rotor back to a scalar field, someone writes bridge code. Indices get repacked. Loops get rewritten. The contraction lives in one library, the rotation in another, the per-vertex traversal in a third. Each crossing hides bugs, and each library brings conventions that clash with its neighbour’s.
A unified surface removes the tax. When a tensor, a matrix, a multivector, and a manifold all implement the same operations, they compose the way they compose on paper. A walk over a mesh, a contraction on a per-vertex tensor, a rotation by a Clifford rotor, and an audit-logged monadic step come from one vocabulary rather than four libraries that need translating.
Four consequences follow:
- One composition law applies everywhere.
fmap,bind,extend, andextractmean the same thing on a tensor, a matrix, a multivector, a manifold, or a propagating effect. - Cross-domain pipelines stay readable. A mesh walk, a tensor contraction, and a rotor application share a single closure. The structure of the code matches the structure of the math.
- The working type is a parameter. Every container honours the same tower, so a model names its scalar once.
FloatTypeselects precision for ℝ;IntTypeselects range for ℤ. - Algebraic laws are compile-time promises. A type that is not associative cannot reach a bound that requires associativity. The compiler enforces what a mathematician would otherwise check by hand.
The crate map
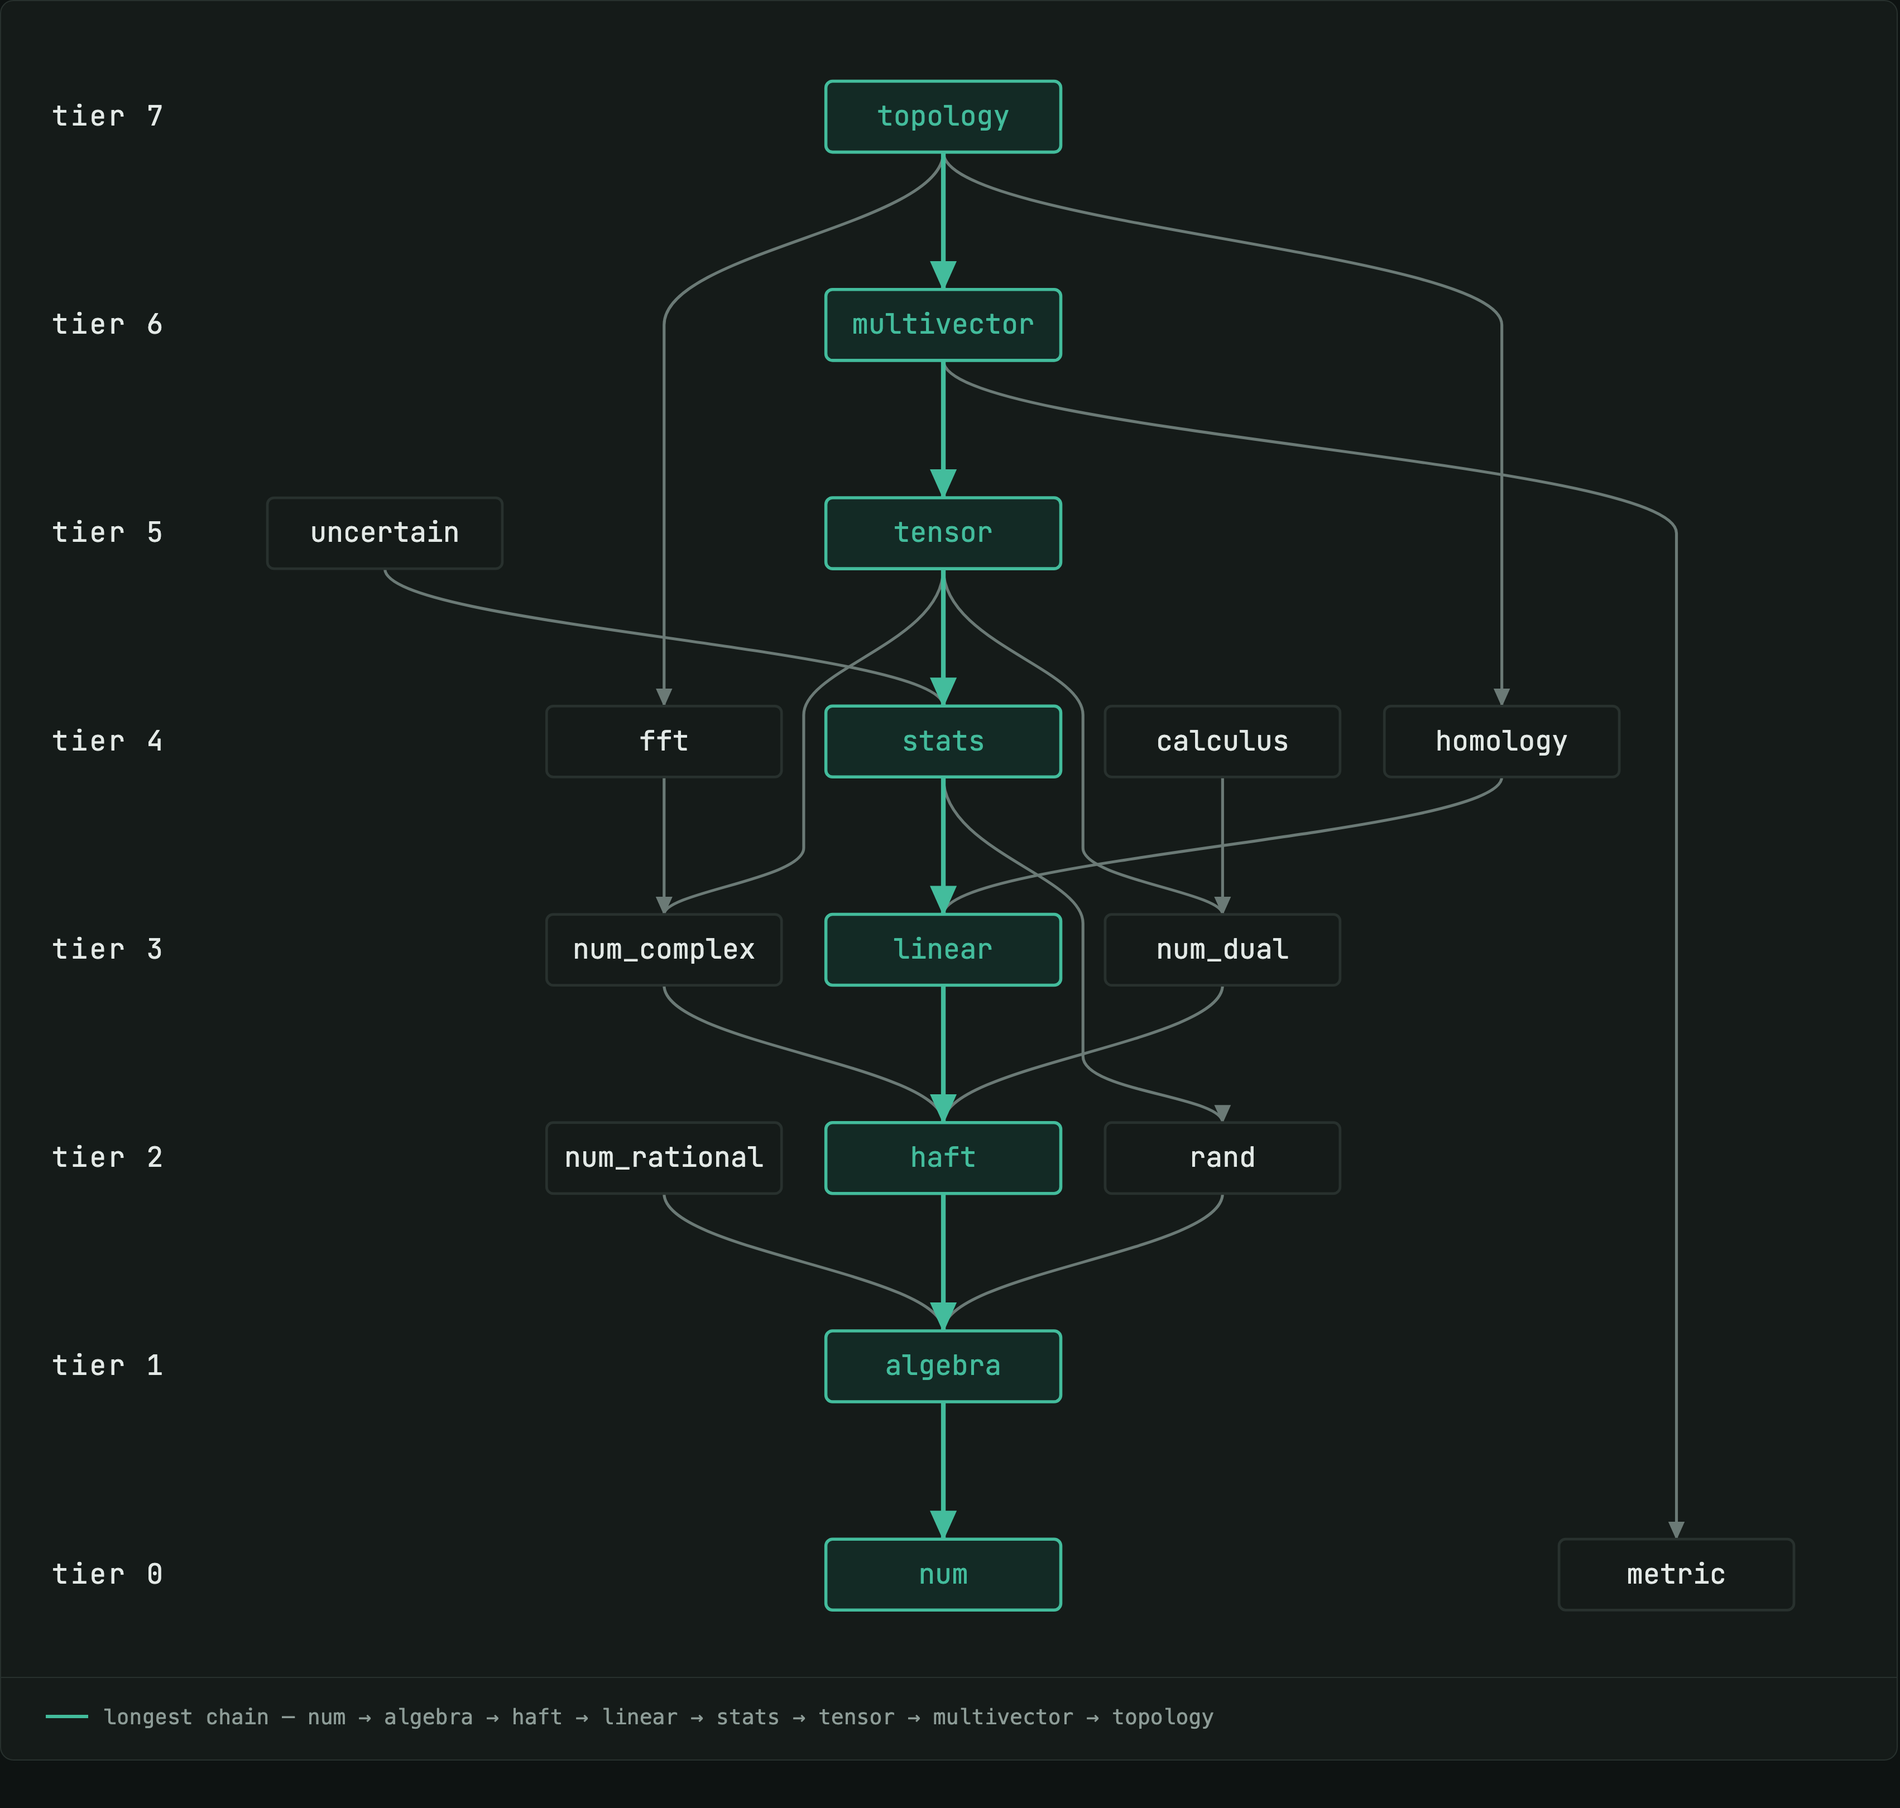
Section titled “The crate map”Seventeen crates carry the mathematics, arranged so that each depends only on crates below it.
| Tier | Crate | Owns |
|---|---|---|
| 0 | deep_causality_num |
representation traits: Integer, NaturalNumber, Float, casts, identities, the two software scalars BFloat16 and Float106, and the lifts that make precision a parameter |
| 0 | deep_causality_metric |
metric signatures Cl(p, q, r), East/West Coast conventions, signature algebra |
| 1 | deep_causality_algebra |
the trait tower from Magma to RealField, the scalar traits, isomorphism markers |
| 2 | deep_causality_haft |
HKT through HKT5, Functor/Applicative/Monad/CoMonad/Foldable/Traversable/DiagonalTraversable/Collectable, Arrow, Category, Kleisli, Free/Cofree, the effect system |
| 2 | deep_causality_num_rational |
Rational<T>, exact ℚ |
| 2 | deep_causality_rand |
entropy and nothing else: generators, the raw machine word, the Boolean draw, Sobol sequences, range sampling. It names no density |
| 3 | deep_causality_linear |
matrices (sparse, dense, bit-packed 𝔽₂), vectors, eliminations, decompositions, solvers |
| 3 | deep_causality_num_complex |
Complex, Quaternion, Octonion |
| 3 | deep_causality_num_dual |
Dual, forward-mode automatic differentiation |
| 4 | deep_causality_calculus |
differentiation, integration, quadrature as Arrow operators |
| 4 | deep_causality_fft |
FFT, rFFT, DCT, N-dimensional plans |
| 4 | deep_causality_homology |
chain complexes, boundary operators, homology over a chosen coefficient field. No geometry |
| 4 | deep_causality_stats |
entropy, log-sum-exp, moments, Pearson, covariance, ridge, logistic IRLS, Gaussian log-density, binning — and the distributions: normal, exponential, Cauchy, Weibull, log-normal, Poisson, categorical, Bernoulli |
| 5 | deep_causality_tensor |
N-index tensors, broadcasting, Einstein summation, the tensor-train stack |
| 5 | deep_causality_uncertain |
uncertain values as lazy computation graphs, generic in the scalar; the graph is an Arrow |
| 6 | deep_causality_multivector |
Clifford algebras, CausalMultiVector, CausalMultiField |
| 7 | deep_causality_topology |
complexes, manifolds, exterior calculus, lattice gauge fields |
Three placements look surprising and are not. num_complex and num_dual sit above num_rational because they ship higher-kinded witnesses over their number types and so depend on haft, which num_rational does not; that lifts calculus and fft with them. tensor and uncertain sit above stats because both take their statistics from it rather than carrying their own, which is what puts stats on the longest chain. And stats depends on rand, the one edge in the figure that skips a tier downward, because the shaped distributions live beside the densities that define them.
That last edge is a coherence fact rather than a preference. A blanket impl<T: RealField> Distribution<T> for StandardUniform is error[E0119] against the u64, u32 and bool implementations a generator must also provide: the compiler cannot prove u64 will never be a real field. Separating what a word is from what a number is distributed as removes the overlap rather than working around it, and the crate boundary is where that separation is cheapest, because stats has no reason to sample a machine word. The direction is downhill, tier 4 to tier 2, so nothing circles back, and stats re-exports the generator traits by name so a crate that wants to draw from a distribution needs no second dependency to spell the bound.
Four crates that consume this stack stay outside the folder, at the repository root. deep_causality_quantum builds density matrices, channels and gates on it; deep_causality_physics supplies physics formulas and engineering primitives, and deep_causality_cfd builds fluid solvers on those; deep_causality_algorithms and deep_causality_discovery run the discovery kernels. They are consumers, not members.
Three properties of that graph do real work. Nothing above tier 1 defines a scalar trait of its own, so there is one answer to “what laws does this number obey” rather than one per crate. No crate depends on a crate above it, so a decomposition written in deep_causality_linear can be called by tensor, multivector, topology and physics without any of them knowing about the others. And nothing here carries a required external dependency: four crates have an optional one, num for libm, rand for getrandom, and fft and topology for rayon, all behind feature gates that are off by default.
The algebraic trait tower
Section titled “The algebraic trait tower”The tower states laws, not representations. The trait names follow standard abstract algebra, and the shape that matters most is that it branches:
Magma → Semigroup → Monoid → Group → AbelianGroup │ │ ┌───────────────┘ │ ↓ ↓ Semiring Ring ↓ ↓ CommutativeSemiring CommutativeRing ↑ ┌───────────┼───────────┐ ℕ ↓ ↓ ↓ IntegralDomain Real Field ↓ ↘ ↙ ↘ EuclideanDomain RealField ComplexField<R> ↑ ℤThe two sides are branches rather than one chain. Semiring is Ring with the additive inverses removed, and nothing on the ℕ branch climbs across: 3 - 5 has no value in ℕ, so there is no -a, so there is no AbelianGroup and no Ring.
Field additionally requires InvMon, which is where the multiplicative inverses enter. That requirement is exactly what the integers fail, and supplying it is what passing to ℚ means.
Beside the structure traits sit Module<R>, Algebra<R>, AssociativeAlgebra<R>, DivisionAlgebra<R>, and AssociativeDivisionAlgebra<R> for vector and division structures. Marker traits (Associative<Op>, Commutative<Op>, Distributive, Annihilating, Invertible, Idempotent) make laws compile-time promises. The markers are parameterised by their operator, which is what keeps (𝔽₂, ×) commuting from implying anything about (𝔽₂ᵐˣⁿ, ×).
Above them sit the scalar traits the numerical code actually binds on: Scalar, Normed, NormedScalar, ConjugateScalar, Characteristic, DivisibleByIntegers, and FiniteField.
The five plus two number sets
Section titled “The five plus two number sets”Each system has two names. The set name is what you reach for when writing code; the algebraic name says what structure it has.
| Set | Set name | Where | Algebraic name | Concrete types |
|---|---|---|---|---|
| ℕ naturals | NaturalNumber |
num |
CommutativeSemiring |
u8…u128, usize |
| ℤ integers | Integer |
num |
EuclideanDomain |
i8…i128, isize |
| ℚ rationals | Rational<T> |
num_rational |
Field |
Rational<i64>, … |
| ℝ reals | Real |
algebra |
RealField |
BFloat16, f32, f64, Float106 |
| ℂ complex | Complex<T> |
num_complex |
ComplexField<R> |
Complex<f64>, … |
A number system needs a crate of its own only when it introduces a type Rust does not have. That is why ℂ and ℚ have crates and ℕ, ℤ, and ℝ do not.
Three further types round out the tower without being number systems. Gf2 is the two-element field, and it is a Field in full standing, which is what lets one elimination serve 𝔽₂ and ℝ. Float106 is double-double arithmetic, about thirty-one decimal digits, and BFloat16 is the top sixteen bits of an f32. Both are built in deep_causality_num and reach the tower through the same Float implementations, so each is an ordinary RealField rather than a special case.
Reach for the set name by default. Reach for the algebraic name when the code needs a structure rather than a set. That is what lets one Field bound serve ℚ, ℝ, and ℂ at once, and one CommutativeRing bound serve ℤ and ℝ together.
Where each type stops, and why
Section titled “Where each type stops, and why”The gaps carry as much information as the entries, because each one is a law that does not hold:
| Type | Highest structure | Where it stops, and why |
|---|---|---|
BFloat16, f32, f64, Float106 |
RealField |
the analytic axis: sqrt, exp, ln, sin |
Complex<T> |
Field + ComplexField<T> |
not ordered, so not a RealField |
Gf2 |
Field + FiniteField |
characteristic 2, so DivisibleByIntegers is absent |
Rational<T> |
Field |
not a Real: no rational sqrt(2), exp, or ln |
i8…i128, isize |
CommutativeRing + EuclideanDomain |
not a Field: 1/5 is 0, so 5 · (1/5) is 0, not 1 |
u8…u128, usize |
CommutativeSemiring |
not a Ring: 3 - 5 has no value in ℕ, so no additive inverses |
Quaternion<T> |
DivisionAlgebra<T> |
not Commutative, so not a field |
Octonion<T> |
DivisionAlgebra<T> |
not Associative either |
Dual<T> |
Real |
not a Field: ε is a zero divisor |
Two of those pairs mirror each other exactly. ℤ is exact and ordered and has no inverses; ℚ supplies the inverses and gives up the analytic axis. Rational is a field without being analytic, and Dual is analytic without being a field.
The stopping points above are not documentation claims. Field for an integer type, Ring for an unsigned type, and Real for a rational are each a compile error. The laws themselves are machine-checked; see Formalization.
Bounding on the weakest law that works
Section titled “Bounding on the weakest law that works”The tower earns its keep at the call site. Every operation in the numeric crates is bounded on the weakest trait that makes it correct, which is what admits the integers and 𝔽₂ rather than only the floats. deep_causality_linear is the clearest case:
| Operation | Bound | Admits |
|---|---|---|
| transpose, dot product | CommutativeSemiring |
ℕ upward |
entrywise subtraction, Module<R> |
CommutativeRing |
ℤ upward |
determinant_exact, rank_exact |
EuclideanDomain |
ℤ only |
rref, rank, kernel and image bases |
Field |
𝔽₂, ℚ, ℝ, ℂ |
determinant, solve, the norms |
NormedScalar |
ℝ, ℂ, the software scalars |
| SVD, QR, Hermitian eigen, Cholesky | ConjugateScalar |
ℝ, ℂ, Dual |
The determinant is a polynomial in the entries and needs no division, so it is defined over any commutative ring. Gaussian elimination divides by its pivot and leaves ℤ on the first step. Both facts are in the bounds, and the exact integer path uses fraction-free Bareiss elimination so that no float appears at any point.
The working type as a parameter
Section titled “The working type as a parameter”Numeric code is written against the algebraic bound and names a concrete type through a single alias. Both aliases live in deep_causality_core:
pub type FloatType = f64; // the precision parameter for ℝpub type IntType = i64; // the range parameter for ℤEvery example in examples/mathematics_examples exposes its own FloatType near the top of main.rs. Edit the line, and the program re-runs at the new precision. There is no parallel implementation and no second copy of the math.
The two aliases are not the same kind of knob, and the difference decides how code around them is written.
FloatType selects precision. Four real types approximate the same set ℝ, and the choice trades accuracy against cost. The failure mode is rounding: a graded error, bounded by epsilon(), which the tolerance machinery can carry and reason about.
| Type | Size | Significand | Exponent | Machine ε | Decimal digits |
|---|---|---|---|---|---|
BFloat16 |
2 bytes | 8 bits | 8 bits | 7.8e-3 |
2 |
f32 |
4 bytes | 24 bits | 8 bits | 1.2e-7 |
7 |
f64 |
8 bytes | 53 bits | 11 bits | 2.2e-16 |
16 |
Float106 |
16 bytes | 106 bits | 11 bits | 4.9e-32 |
31 |
Precision is the significand and range is the exponent, and the two move independently. The ε column spans nine orders of magnitude; the range takes only two values, 3.4e38 for the two narrow types and 1.8e308 for the two wide ones. BFloat16 therefore holds every magnitude f32 holds and resolves fewer of them, while Float106 resolves more than f64 over the same magnitudes. Float106 costs roughly two to four times an f64 operation. BFloat16 computes in f32 and rounds once, which is harmless for +, -, *, / and sqrt, and a slice of it is byte-compatible with the bf16 buffers accelerators exchange.
Three kinds of number cross the boundary of that alias, and the obvious spellings each fail on one of the four. x as FloatType casts between primitives only, so it stops compiling the day the alias becomes Float106, and FloatType::from(0.5) compiles for f64 and Float106 but not for f32, which has no From<f64>. The lift module writes the crossings once over FromPrimitive and ToPrimitive: lift for a configuration literal, lift_count for a count, lower at the display boundary, and to_count back to a rounded integer. Each has a try_ form returning Option rather than panicking.
IntType selects range. Every signed width represents a finite window of ℤ exactly, so there is no rounding and no analogue of epsilon(). The failure mode is overflow, which is not a graded error but a hard wrongness, because the computed value is not an approximation of the true one. Widening IntType buys headroom rather than accuracy, and integer code carries an explicit overflow discipline (checked, saturating, or wrapping) where float code carries a tolerance.
IntType is signed because ℤ requires additive inverses. The unsigned types have none, so they are a commutative semiring rather than a ring. Counting and indexing use NumberType, which is what ℕ is for.
The composition surface
Section titled “The composition surface”Rust has no native Higher-Kinded Types. HAFT adds them with a witness pattern: a zero-sized struct that stands in for the type constructor. Code generic over the witness picks up any container implementing the same functional trait.
fn double_value<F>(m_a: F::Type<i32>) -> F::Type<i32>where F: Functor<F> + HKT,{ F::fmap(m_a, |x| x * 2)}double_value::<OptionWitness>(Some(5)), double_value::<VecWitness>(vec![1, 2, 3]), and double_value::<CausalTensorWitness>(tensor) all type-check, all run, and none allocate for the witness itself.
The HKT trait carries an associated Constraint, so a witness can restrict which element types it admits:
pub trait HKT { type Constraint: ?Sized; type Type<T> where T: Satisfies<Self::Constraint>;}Most math containers use NoConstraint and accept any element. The constraint slot is what lets a container demand a physics-valid scalar instead.
The math witnesses
Section titled “The math witnesses”The table below lists every math container that joins the surface. Read a row as one container: the crate that owns it, the type, the witness that stands for its constructor, and the functional traits that witness implements. The rightmost column is the useful one, because it says exactly which operations are available on that container and, by omission, which are not.
| Crate | Container | Witness | Implements |
|---|---|---|---|
linear |
CsrMatrix<T> |
CsrMatrixWitness |
Functor, Foldable, Pure, Applicative, CoMonad |
linear |
DenseMatrix<T> |
DenseMatrixWitness |
Functor, Foldable, Pure, Applicative, CoMonad |
linear |
DenseVector<T> |
DenseVectorWitness |
Functor, Foldable, Pure, Applicative, Monad, CoMonad |
tensor |
CausalTensor<T> |
CausalTensorWitness |
Functor, Foldable, Pure, Applicative, Monad, CoMonad |
tensor |
CausalTensor<T>, zipped |
ZipTensorWitness |
Functor, Semigroupal, MonoidalApplicative, Convolutional |
tensor |
CausalTensorTrain<T> |
CausalTensorTrainWitness |
Functor, Foldable, Pure |
multivector |
CausalMultiVector<T> |
CausalMultiVectorWitness |
Functor, Foldable, Pure, Applicative, CoMonad |
multivector |
CausalMultiField<T> |
CausalMultiFieldWitness<T> |
Functor, Pure, CoMonad |
topology |
Manifold<C, F> |
ManifoldWitness<C> |
Functor, Foldable, Pure, Applicative, Monad, CoMonad |
topology |
any ChainComplex |
GenericManifoldWitness<K> |
Functor |
core |
PropagatingEffect<T> |
PropagatingEffectWitness<E, L> |
the causal-monad stack |
deep_causality_topology ships twelve witnesses in total. Beyond the two listed, they cover graphs, hypergraphs, mixed graphs, cell complexes, lattice complexes, point clouds, chains, boundaries, and exterior derivatives.
Where the surface stops, deliberately
Section titled “Where the surface stops, deliberately”A witness claims a trait only when the laws hold. Two absences carry weight.
The shaped containers are not monads. DenseMatrix and CsrMatrix stop at Applicative and CoMonad. A shaped container cannot satisfy the monad laws: pure has to choose a shape for a single value, and right identity bind(m, pure) == m then asks bind to reassemble an m × n matrix from m · n one-by-ones. DenseVector does claim Monad and satisfies it, because its only shape is its length.
A sparse fmap maps the stored entries. CsrMatrixWitness::fmap leaves the structural zeros alone, which keeps the result sparse. A function that does not fix zero therefore changes the matrix that is represented, and a caller who wants it applied to the whole logical matrix densifies first. The conversion is written at the call site so its cost stays visible.
Adjunctions
Section titled “Adjunctions”An adjunction is a typed bridge between two categories, so a problem stated in one can be carried to the other without hand-written glue. One is implemented.
Adjunction<ExteriorDerivativeWitness, BoundaryWitness, StokesContext<T>> is Stokes’ theorem as an adjunction: ⟨dω, C⟩ = ⟨ω, ∂C⟩. The left adjoint is the exterior derivative on differential forms, the right adjoint is the boundary operator on chains, and the context is the simplicial complex that gives both their discrete meaning. Conservation laws and discrete integration theory are downstream of it.
A second adjunction, from CausalMultiVectorWitness to itself across a metric signature, used to sit beside it and has been removed. It claimed a multivector is adjoint to itself, with unit broadcasting one value across every blade and counit reading the first coefficient back. That pair cannot satisfy the defining bijection: the round trip reconstructs a constant multivector, so it is the identity only where the input already holds the same value in every blade. With ctx = Euclidean(1) and [3, 4] it returns 3 where the law requires 4. No unit can do better, because it is handed a single value and must fill 2^dim coefficients. The rule the crate follows is to drop a structure whose laws fail rather than ship it.
The same rule cost CausalMultiVectorWitness its Monad. No metric choice satisfies both identity laws, so the witness stops at Applicative and CoMonad. CausalTensorWitness kept its Monad by being fixed instead: bind now preserves the input’s shape when the map is shape-preserving, so a [2, 3] no longer comes back as [6].
The math layers
Section titled “The math layers”The witness table lists each container in one row. This section gives each layer its shape: what is in the box, and when to reach for it.
Linear algebra: deep_causality_linear
Section titled “Linear algebra: deep_causality_linear”Three matrix representations behind one read trait, so the choice of storage is a local decision. CSR for data that is large and mostly zero (boundary and coboundary operators, discrete Laplacians, adjacency). Dense row-major for the small square problems the decompositions act on. Bit-packed 𝔽₂ for mod-2 elimination, where a whole row updates in one word operation. A dense vector sits alongside them, and it carries the larger half of the workload: a census across the consumer crates counted 60 rank-1 constructions against 46 rank-2.
The eliminations come in pairs, because the pivot rule cannot be chosen by the representation alone. The exact rule takes the first non-zero and needs no ordering and no epsilon, which is how 𝔽₂ and ℚ get through. The _stable rule takes the largest modulus, which is what a float caller wants. Both search the column; neither takes the diagonal on faith, and that is load-bearing, since a Cayley-Menger matrix has a zero in the corner by construction.
The decompositions (Hermitian eigen, thin Householder QR, one-sided Jacobi SVD, Cholesky) are bounded on ConjugateScalar, which spans real fields, dual numbers for forward-mode AD, and complex. Magnitudes and thresholds live in the associated real type and only the rotations are injected back, so a Hermitian complex matrix decomposes as readily as a real symmetric one.
Tensors: deep_causality_tensor
Section titled “Tensors: deep_causality_tensor”N-index arrays with a stride-based layout, broadcasting for element-wise operations, and Einstein summation for products and contractions. Reach for tensors wherever the math is rectangular data: relativistic field tensors, Kalman state and covariance, per-cell fields.
Above the dense tensor sits the tensor-train stack. CausalTensorTrain stores a high-order tensor as a chain of rank-3 cores, so the element count grows linearly with the order instead of exponentially, and CausalTensorTrainOperator is the matrix-product operator that maps one train to another. Both are generic over the scalar through ConjugateScalar, so the same code runs at f32, f64, and Float106, at Dual for forward-mode AD, and at Complex for the Hermitian stack.
Multivectors and geometric algebra: deep_causality_multivector
Section titled “Multivectors and geometric algebra: deep_causality_multivector”Clifford algebras over the dynamic signature space, with constructors for Pauli, Spacetime Algebra, Conformal Geometric Algebra, Projective Geometric Algebra in 3D, the Dixon algebra of Standard Model particle physics, and the Grand Unified Algebra hosting Spin(10). Dimension-changing composition, the tensor product of algebras, is an explicit geometric operation rather than a monadic bind, because the witness does not claim Monad.
CausalMultiField extends the type from a single multivector to a field of them over a grid, with its own differential operators, batched matrix multiplication, and gamma-matrix machinery.
The payoff is concrete. The Maxwell example expresses the electromagnetic field F = ∇A as one multivector and recovers E and B as its bivector grades. Where vector calculus needs separate cross products, exterior derivatives, and Hodge stars, the geometric product handles it as one operation on one object.
Topology and differential geometry: deep_causality_topology
Section titled “Topology and differential geometry: deep_causality_topology”Graphs, hypergraphs, simplicial complexes, lattice (cubical) complexes, general cell complexes, manifolds, and point clouds. A single ChainComplex trait carries cell iteration and the boundary and coboundary matrices, and the differential operators read ∂ and δ through it, so the same operator code runs on the simplicial and cubical paths.
The layer carries first-class exterior calculus: exterior derivative d, Hodge star ⋆, codifferential δ, and the Hodge-Laplacian, with a boundary-corrected star on wall-bounded lattices that keeps the operators symmetric positive semi-definite. Poisson solves and Leray projections dispatch over three domain classes: fully periodic uniform boxes solve directly by rFFT, wall-bounded uniform boxes solve directly by DCT-I, and everything else falls back to Jacobi-preconditioned conjugate gradient.
The lattice gauge field framework supports U(1), SU(2), SU(3), and Lorentz gauge groups and is verified against 24 reference results from Creutz’s Quarks, Gluons and Lattices.
Manifold is the layer’s CoMonad, which is what makes extend (apply a function to every local neighborhood) and extract (read the value at the current point) first-class on geometric data. Graph convolutions and cellular automata become one comonadic walk over a typed neighborhood.
Homology: deep_causality_homology
Section titled “Homology: deep_causality_homology”Chain complexes and nothing else. A complex is spaces C_k joined by boundary maps ∂_k obeying ∂_k ∂_(k+1) = 0, and homology is cycles modulo boundaries, H_k = ker(∂_k) / im(∂_(k+1)), whose dimension is the Betti number. betti_number_over picks its coefficient field through HomologyField, taking an exact integer elimination on the rational path and a mod-2 reduction on the binary one; the coefficient choice can change the answer. There is no geometry here at all, which is the point: a quantum error-correcting code is a chain complex with no cells, so it uses this crate without ever constructing a mesh.
Statistics: deep_causality_stats
Section titled “Statistics: deep_causality_stats”Descriptive and information statistics over slices: moments, Pearson correlation, covariance, conditional variance, entropy, log-sum-exp, Gaussian log-density, ridge regression, logistic IRLS, proportions, and binning. The distributions live here too — normal, exponential, Cauchy, Weibull, log-normal, Poisson, categorical, Bernoulli, the unit-interval draws and their inverse-CDF transforms — because a distribution is defined by its density and its moments, and both are statistics. Putting a sampler beside its density is what makes importance sampling, sequential Monte Carlo and MCMC diagnostics short to write.
The crate does not exist to remove duplication; it adds more source than it removes. It exists because shipped implementations of the same statistic disagreed about what they computed. Shannon entropy decided it: three implementations in this workspace differed on three axes at once, and two returned answers in different units for the same input, one in bits and one in nats, a factor of ln 2 apart. That is a semantic disagreement rather than a rounding difference. So the configuration types keep the semantics explicit rather than implied — entropy names its log base, its normalization and its zero-handling policy, and sample and population variance are separate functions — and every combination named in EntropyConfig has a caller today.
tensor and uncertain both hand their reductions here rather than growing their own, which is what lifts this crate onto the longest chain.
Metric signatures: deep_causality_metric
Section titled “Metric signatures: deep_causality_metric”One horizontal crate defining signatures once: Euclidean(n), NonEuclidean(n), Minkowski(n) (West Coast, mostly minus), Lorentzian(n) (East Coast, mostly plus), PGA(n) with a degenerate generator, and the explicit Cl(p, q, r). Signatures compose (tensor_product), convert (east_to_west, west_to_east), and report their own (p, q, r). Because the crate has no dependencies at all, every layer above can name a signature without pulling anything in.
Differentiation, integration, and quadrature: deep_causality_calculus
Section titled “Differentiation, integration, and quadrature: deep_causality_calculus”The analytic operators of the Causal Arrow. Differentiation is the tangent functor. You write a model once as a DifferentiableArrow, or as a multi-input DifferentiableField<N>, whose run is generic over the scalar. The fluent methods then seed and read the dual channel for you, so that Dual, ε, and seeding never surface: derivative, value_and_derivative, second_derivative, gradient, and directional_derivative. Integration is endomorphism iteration: Euler and Rk4 build value-level endo-arrows and iterate them to a fixed horizon, to a fixpoint, or until an event predicate holds. Quadrature is composite Simpson’s rule, exact through cubics; run it over Dual and the result carries the Leibniz rule.
The derivative view Diff is an ordinary Arrow and composes with the same compose/first/split/fanout combinators as the rest of the Arrow algebra.
Fast Fourier transforms: deep_causality_fft
Section titled “Fast Fourier transforms: deep_causality_fft”Plan-based forward and inverse transforms, generic over RealField and operating on Complex data. FftPlan handles 1-D complex transforms of any length, RfftPlan the real-to-complex case, and FftPlanNd / RfftPlanNd the N-dimensional case. DctPlan adds cosine transforms of types I to III, the building block for Neumann-Poisson solves on wall-bounded boxes.
The planner picks its algorithm by length: hardcoded kernels from 2 to 32, a mixed radix-4/radix-2 Stockham pipeline for larger powers of two, and Bluestein’s chirp-z method for everything else. The cost therefore stays O(N log N) at every size. Twiddles are computed per index rather than by recurrence, so a transform is as accurate as the scalar’s sin/cos, which is what makes Float106 yield genuinely extended precision rather than f64-limited results.
The crate exists for one job: to give the DEC-native Navier-Stokes solver a spectral Poisson solve on periodic lattices. There it replaced a conjugate-gradient Leray projection that dominated the 388 ms (32³) solver step, cutting that projection to about 1.9 ms.
Uncertainty: deep_causality_uncertain
Section titled “Uncertainty: deep_causality_uncertain”Uncertain<R> is a lazy computation graph, generic in its scalar under RandScalar. Arithmetic and comparison extend the graph rather than collapsing it to a number, and evaluation samples it to a requested confidence. MaybeUncertain<R> factors a reading into presence and value, so a sensor that reports eighty percent of the time is a different object from one that reports five percent of the time.
The graph is an Arrow, not a container. haft’s container traits carry no 'static bound, deliberately: a functor receives a function, applies it and drops it. A carrier that stores a sampling closure needs bounds those traits do not provide, and an implementation cannot add them. So a lazy sampler cannot be a witness, and haft’s home for programs is Arrow, which Uncertain<R> and UncertainBool<R> implement with In = SampleIndex and Out = Result<R, UncertainError>. Arrow::run takes &self, which is admissible only because a draw is a pure function of three numbers — the session seed, the sample index and the leaf’s ordinal — and of nothing else. Nothing is stored between calls, which is also why x - x is exactly zero: a leaf reached twice within one graph is one draw.
Ensembles go the other way and are ordinary data. materialize::<W> takes a witness and hands back W::Type<R> — a DenseVector<R>, a rank-1 CausalTensor<R>, a Vec<R> — so the draws arrive already carrying every categorical structure that witness provides, and the crate declares no ensemble type and names neither container crate. Two ensembles drawn from one session at the same indices are correlated by index, so combining them is a positional zip (Semigroupal::zip_with, DiagonalTraversable::sequence_zip) rather than Traversable::sequence, which forms the cartesian product: four quantities at fifty draws each give 50⁴ = 6 250 000 combinations instead of fifty correlated tuples.
Every path runs at f32, f64 and Float106 alike, which keeps rounding error separate from the uncertainty being modelled. Uncertainty covers the decision API.
Randomness: deep_causality_rand
Section titled “Randomness: deep_causality_rand”Entropy, and no distributional claim. What this crate supplies is a source of numbers — Xoshiro256, an OS-entropy generator, a Sobol sequence — together with the draws that are facts about the bits themselves: a raw machine word, a Boolean, and a value uniform over a range. None of those is a density. Nothing here states a mean, a variance or a moment, and the shaped distributions live in deep_causality_stats instead.
The float draws are generic in the scalar under RandScalar, with one body and no per-type implementation: the loop stops when the next word would land entirely below the scalar’s own resolution, which Real::epsilon already reports, so f32, f64 and BFloat16 take one word and Float106 takes two, and a scalar added tomorrow takes however many it needs on the day it arrives. Topology uses this crate for gauge-field thermalization; the discovery algorithms use it for resampling.
A concrete example: GRMHD
Section titled “A concrete example: GRMHD”The grmhd example couples a general-relativity solver to a plasma physics solver, picks a metric signature from local spacetime curvature, computes the Lorentz force in the selected geometry, and feeds the electromagnetic stress-energy back into the metric. Every step lives in a different mathematical regime. They compose as one chain:
CausalFlow::value(GrmhdState::new(&config)) .next(|s| { // [Step 1] GR solver — tensor algebra. // Builds the Schwarzschild metric g_uv and the Ricci tensor, // contracts them into the Einstein tensor G_uv = R_uv - ½ R g_uv. model::calculate_curvature(s).into() }) .next(|s| { // [Step 2] Causal coupling — metric-signature selection. // Branches on curvature intensity and picks Metric::Minkowski(4) // or Metric::Euclidean(3). model::select_metric(s).into() }) .next(|s| { // [Step 3] MHD solver — Clifford algebra. // Wraps the current J and magnetic field B as CausalMultiVector // in the metric chosen above, then computes F = J ∧ B as a bivector. model::calculate_lorentz_force(s).into() }) .next(|s| { // [Step 4] GRMHD coupling — back to tensor algebra. // Builds the EM field strength tensor F^uv and contracts it with the // spacetime metric g_uv from Step 1 to produce T^uv. model::calculate_energy_momentum(s).into() }) .next(|s| { // [Step 5] Stability analysis — scalar branching on bivector intensity. model::analyze_stability(s).into() }) .run(print_conclusion, |err| eprintln!("Simulation failed: {err:?}"));Look at what the chain crosses. Step 1 is tensor algebra in deep_causality_tensor. Step 2 makes a runtime decision in deep_causality_metric that changes the geometry of the next step. Step 3 leaves tensor algebra for Clifford algebra in deep_causality_multivector. Step 4 returns to tensor algebra, now coupled to the metric produced in Step 1, which is what closes the feedback loop. Step 5 is ordinary Rust.
CausalFlow hands the raw state to each step and short-circuits on the first error, so a failure in Step 2 never reaches Step 3 and never gets swallowed by a default value. CausalTensor, CausalMultiVector, and Metric are all instances over the same carrier, so each stage consumes a GrmhdState and returns one regardless of which regime it works in. The pipeline reads like the physics: curvature, then metric selection, then Lorentz force, then stress-energy, then stability.
The mathematics_examples tree extends the same composition three more ways. A Kalman predict-correct chain mixes tensor and rotor steps. A heat equation alternates extend for the spatial Laplacian with bind for the time step. The relativistic_spinor_transport example parallel-transports a unit timelike spinor through Cl(3,1) along a discretized worldline.
Precision, measured
Section titled “Precision, measured”Two programs measure what the alias is worth. The first sums a million terms of a telescoping series whose closed form is known, so the rounding the loop accumulates can be read out as digits:
FloatType |
Error after a million terms | Correct digits |
|---|---|---|
BFloat16 |
3.1e-2 |
2 |
f32 |
1.5e-4 |
4 |
f64 |
4.8e-14 |
13 |
Float106 |
9.8e-31 |
30 |
The two narrow types stop adding rather than merely rounding. A term below half a unit in the last place of a sum near one vanishes on addition, so BFloat16 stalls at 0.96875 after twenty-three terms and never moves again, and f32 stalls once k passes four thousand. f64 keeps every term and rounds a million times, and those roundings partly cancel. Float106 earns seventeen digits over f64 for one changed line.
The second is the capstone, which parallel-transports a unit timelike spinor along a discretized Minkowski worldline through four boost steps, then compares the composed result against cosh(θ), sinh(θ) for the summed rapidity:
| Precision | Composition drift |
|---|---|
f64 |
~1.1 × 10⁻¹⁶ |
Float106 |
~1.7 × 10⁻³¹ |
Fifteen orders of magnitude, recovered by editing one line. The algorithm, the topology, the Clifford rotor, and the monadic chain are unchanged.
When the dial actually matters
Section titled “When the dial actually matters”Switching precision is cheap; deciding whether you need it is the real question. The rule from these examples is that drift widens with precision only when there is a multi-step, non-rational, transcendental computation.
| Workload shape | Reach for | Why |
|---|---|---|
| Integer or simple-fraction arithmetic | f32 or f64 |
Both are exact for the relevant values. Float106 buys nothing and costs runtime. |
| A single transcendental step | f64 |
One rounding event near 10⁻¹⁶ sits under any modelling error. |
| Time-stepping on smooth fields with bounded operator norm | f64 |
Error per step is small and the operator damps it. |
| Chained transcendental composition: parallel transport, repeated rotor application, Lie-group accumulation, long Kalman cascades | Float106 |
Each step contributes f64 rounding and the chain amplifies it visibly. |
| Ill-conditioned linear algebra: near-singular matrices, narrow eigengaps | Float106 |
The condition number multiplies rounding error; extra mantissa bits buy the digits back. |
| Verification and regression baselines | Float106 |
The point is to expose error in the f64 path, so this is the oracle to diff against. |
The capstone sits in the chained-transcendental row and visibly benefits. The Laplacian and diffusion examples sit in the rational-arithmetic row and gain nothing observable. Do not default to Float106 because it sounds safer; default to f64 and reach for more when the structure of the computation amplifies rounding error.
Because the right answer differs from one part of a simulation to the next, precision is worth choosing per part against a stated error budget: a noise-bound Monte Carlo integral whose error is the statistical 1/√n gains nothing above f32, a mesh-bound difference balances truncation against rounding at f64, and a conservation budget accumulated over a whole run wants Float106 and costs almost no memory, being a reduction. The crate README works that trade through on a weather-forecast ensemble.
What the unification enables
Section titled “What the unification enables”The HKT machinery, the witness inventory, and the algebraic tower are three layers of one architecture. Read in isolation each looks like an implementation detail. Together they give the library a property that conventional scientific stacks struggle to deliver.
A single closure can walk a mesh, contract a tensor, apply a Clifford rotor, solve a sparse system, accumulate state, append to an audit log, and short-circuit on error, in any order, with no glue between the layers. The composition law that makes the closure work is the same law that composes a stateless bind chain, a contextual Causaloid graph, a manifold extension, and a PropagatingEffect returned from the Effect Propagation Process. The math, the data structures, and the runtime speak one language.
See also
Section titled “See also”- Folder overview:
deep_causality_unified_math/README.md, which carries the dependency graph, the precision experiments, and the mixed-precision study. - Reference READMEs:
num,algebraand its trait reference,haft,linearand its scenario guide,tensor,multivector,topology,homology,stats,uncertain,calculus,fft,num_rational. - Examples:
examples/mathematics_examplescovers HKT composition (tensor_x_algebra_rotation_field,manifold_laplacian_stencil,structural_stress_on_mesh), causal-monad composition (effect_kalman_predict_correct,diffusion_space_and_time,effect_tensor_algebra_roundtrip), and theCl(3,1)spinor capstone. Each names itsFloatTypeat the top ofmain.rs, so any of them re-runs at another precision from one edit. - Concepts: Higher-Kinded Types, Causal Monad, Causal Flow, Effect Propagation Process.
- Proofs: Formalization, covering the num, algebra, haft, linear, complex and dual, rational, topology, and quantum layers.